Plans every day
Builds a day-by-day schedule from the exam date and the time available, with catch-up and rest days. Anki schedules cards. This plans the whole day: reviews, reading, questions and practice exams.
March 2026 to now
It began as a personal flashcard tool and has grown into a complete study platform: a daily plan built around the exam date, questions in the AAMC format with detailed explanations, and spaced-repetition flashcards. I lead the product and test every release. A team of AI coding agents writes the code, working to the rules I set.
Quality MCAT preparation costs thousands of dollars, and that cost should not decide who gets into medicine. Students trust the official AAMC questions but find the explanations thin. UWorld explains well, but many students cannot afford it. This app offers both, for free.
Builds a day-by-day schedule from the exam date and the time available, with catch-up and rest days. Anki schedules cards. This plans the whole day: reviews, reading, questions and practice exams.
Passage-based questions in the AAMC format. Each wrong answer is explained step by step.
Each card returns just before it would be forgotten. Anki decks import and export.
Science content comes from OpenStax textbooks. Reading passages are verbatim excerpts from published works.
Writes new questions from textbook sections. Several independent checks review each one, and any of them can reject it.
Runs locally with encrypted storage. Data does not leave the computer unless the student turns that on.
Biology and biochemistry questions mixed with AAMC and UWorld items, sources hidden, scored 1 to 5 by two independent raters.
| Ours | UWorld | AAMC | |
|---|---|---|---|
| Explanation | 4.87 | 4.10 | 3.08 |
| Answer key | 4.73 | 4.80 | 3.78 |
| Reasoning | 4.91 | 5.00 | 4.53 |
| Reads like the exam | 4.96 | 5.00 | 4.95 |
96 cards across six topics, presented identically without labels, scored 1 to 5 by two independent raters.
| Ours | MileDown | AnKing-style | |
|---|---|---|---|
| Correct | 4.60 | 3.92 | 3.56 |
| Depth | 3.02 | 2.13 | 2.71 |
| Pictures | 3.83 | 3.35 | 2.35 |
| Study value | 3.79 | 3.02 | 2.81 |
| Price | What students say | |
|---|---|---|
| AAMC | about $324 | Most like the exam. Thin explanations. |
| UWorld | from $339 | Great explanations. Expensive. |
| Blueprint | $1,499+ | Structured. Lots of video. |
| Anki decks | Free | Huge, but with gaps and errors. |
| This app | Free | Exam-format questions, detailed explanations and a daily plan. |
Select a topic to expand it.
A personal flashcard app, extended with practice exams, a planner and statistics.
Rebuilt on a modern framework, with every existing feature listed first so that every one was kept.
Every screen redesigned. Textbook library, encrypted storage and Anki import added.
Generator built and tested blind against official and commercial questions. Phone companion added.
Completing the full bank ahead of launch to pre-med students at the University of Manitoba.
We built a 3D world for the home screen. It was impressive, but it slowed the app and pulled focus from studying, so I removed it.
Every question and card must trace back to a textbook section. Anything that cannot is discarded.
Every change is tested and approved by a separate reviewer before it is merged.
The app does not require an account and does not use cloud storage. AI features are optional and use the student's own key.
Most apps today are cloud subscriptions that keep your data on their servers. I chose the opposite. Students' study records sit close to health and medical information, and that kind of data should not be sent over the internet without their say. Everything stays on the student's own computer, in an encrypted database (SQLCipher). The app does not require an account, does not use cloud storage, and works fully offline. AI features are optional and use the student's own key, so data is shared only when they choose.
The original app had grown to about 30,000 lines of plain JavaScript and was getting risky to change. I moved it to React, starting from a full feature inventory so that every feature was kept, and old code was retired only after a script confirmed it was unused.
Every rule lives in exactly one place. One module decides what is due for review, and the home screen, study sessions, flashcards and planner all read from it. When two screens work something out separately, they eventually disagree. One owner means one answer and one place to fix.
Scheduling, pacing and planning are pure functions that do not depend on the screen, the clock or storage. They can be tested thoroughly on their own and behave the same wherever they are used.
State is split into four layers: shared logic, encrypted study data, settings and background services. Each screen's state has exactly one owner in the store (Zustand), so any bug traces back to one place.
A saved study plan is out of date the moment a student misses a day. So the plan is not stored. It is recalculated from the student's real progress every time, and every change they make is applied the same way.
Even a local app should limit what can go wrong. The Electron shell runs sandboxed, the interface reaches the system only through an approved list of channels, and every response is checked at that boundary.
The app can work with six AI providers: Anthropic, OpenAI, Google Gemini, Mistral, Groq and Ollama, which runs models on the student's own computer. A router decides which model handles each task. I designed it around one principle: the student's choices always come first, and quality, capability and cost are weighed only within them.
A model the student has pinned is used as is. Otherwise the router stays within their chosen provider, their quality setting and their spending limit.
Each task declares what it requires, such as reading images, reading PDFs, structured output, long documents or keeping data on the computer. Models that cannot do the job are filtered out.
Among the models left, it scores quality for that kind of work and moves up a tier only for harder material, such as difficult questions or answers that must be graded precisely.
If none of the available models meets every requirement, it uses the closest match and tells the student plainly, including what would fix it. It does not fail silently.
The routing decision is a pure function: the same inputs always give the same answer, without side effects, so every rule can be tested directly. Adding a new provider means registering it, not changing the router.
Most study apps are tied to one cloud AI service and send everything to it. This router works across six providers, including one that runs entirely on the student's computer, and it puts the student's choices and data rules ahead of the system's preferences.
Because each decision is a pure function, every rule (pins, capability filters, tier escalation, spending limits, the loud fallback) is checked directly by automated tests, without needing a live AI service.
Generated questions are only useful if they are right. The generator is a pipeline of seven stages, using several AI models and code checks, each with one job. Four of the stages can reject a question, and anything that fails is discarded rather than patched.
Every question starts from one section of a real text: OpenStax for the sciences, published works for reading passages.
The question is planned before it is written: the skill it tests, the reasoning it needs, and the specific mistake each wrong answer is built to catch.
Passage, question, four options and a step-by-step explanation, written only from the source and the blueprint.
A separate model answers without seeing the key. If it does not reach the intended answer, the question is removed.
Every fact the answer depends on must be found in the source text. Anything unsupported is removed.
Fixed checks that a model cannot argue past: format, option letters, explanation steps, giveaway wording and duplicates.
Each batch's mix of skills and difficulty must sit within the real exam's range, and batches are rated blind alongside real exam questions.
I benchmarked the design against 13 published and commercial systems. Research generators rely on templates built by experts or a human reviewer at the end, and commercial banks do not publish how their questions are made. A single AI prompt produces acceptable questions only 18 to 31 percent of the time in a published medical study. This pipeline does not have a human in the loop, so its gates are built to carry that load: every wrong answer is planned around a real mistake, and every fact is checked against the source.
Batches were rated blind, mixed in with official AAMC and commercial questions. On biology and biochemistry, its explanations scored 4.87 out of 5, against 4.10 for UWorld and 3.08 for the AAMC's own. Each round of testing fed the next version of the pipeline.
Simulated students study for a week, a month, a year and several years, on the real encrypted database. They miss days, move their exam date, import decks and rest, and the app is checked every simulated day. One run loads 100,000 cards to test scale.
Automated tests open the real desktop app and study through it for weeks at a time with a controlled clock, then compare the app's plan against an independent calculation every day.
Property tests state rules the planner must always keep, then check them across many randomly generated study histories with missed days, rest days and exam date changes.
A task can only be marked done with a signed record that its tests ran. The system re-runs that command itself, and blocks any commit made with code newer than the last passing test run.
The app's writing rules are checked automatically by the test suite: plain everyday words, without internal jargon, dashes or trailing dots. A screen that breaks them fails the tests.
Every textbook figure carries its source and licence on the card. A licence audit corrected the terms shown across the app.
Every major part was iterated and re-tested until it measured up. The flashcard generator is a good example: the previous version's cards were thin, so it was rebuilt and tested again, blind.
Same blind test, same raters, same six topics.
| Current | Previous version | |
|---|---|---|
| Depth | 3.02 | 1.94 |
| Pictures | 3.83 | 1.35 |
| Study value | 3.79 | 2.50 |
| Correct | 4.60 | 4.40 |
I lead the product. I define the requirements and quality standards, design the interface, and test every release. My biochemistry degree lets me verify the science content directly.
The code is written by a team of AI coding agents (Claude Code and OpenAI Codex), each with a defined role: planning, building, design or review. I set the rules and the review process they work to.
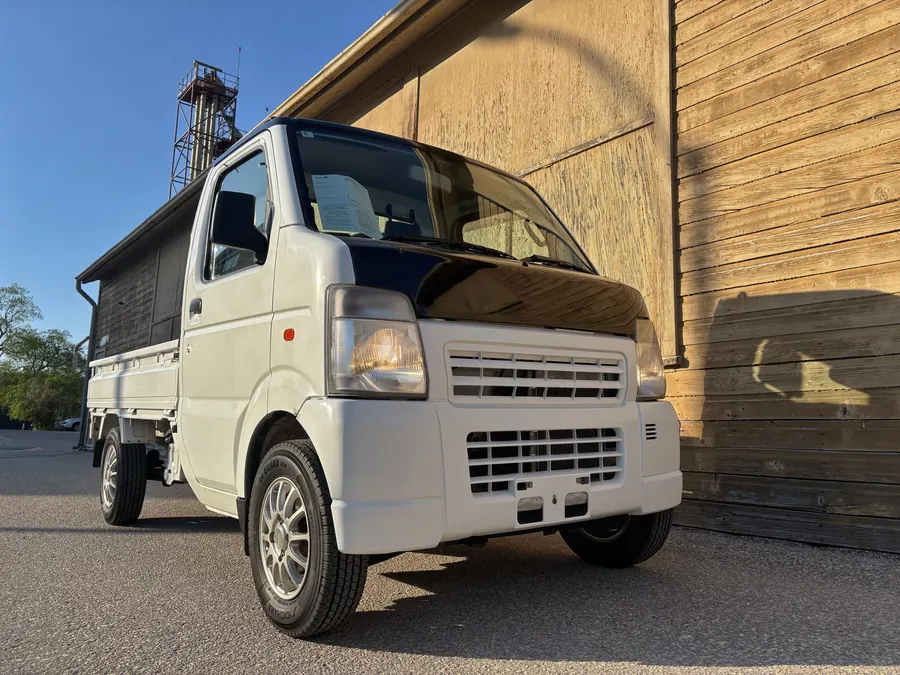
Custom relay lighting circuits that passed Manitoba safety inspection, bodywork and paint, and a complete business plan and website for an import company.
See the vehicle work
I'm open to IT, QA, health technology and laboratory roles in Winnipeg or remote.